The Challenge
Scaling high-stakes assessment marking and quality assurance in a regulated sector is a daunting task. Summative and formative assessments demand absolute precision. But as candidate volumes grow and expert assessor pools shrink, keeping turnaround times fast and standards consistent across thousands of scripts becomes an operational bottleneck.
The pressure to adopt automation is real - but generic language models present huge compliance and reputational risks. Unmonitored, ad-hoc AI tools and black-box algorithms dilute standards, introduce bias, and lack the transparent reasoning required by regulators.
Enterprise-grade assessment intelligence for high-stakes qualifications.

Automated marking against your marking guidance:
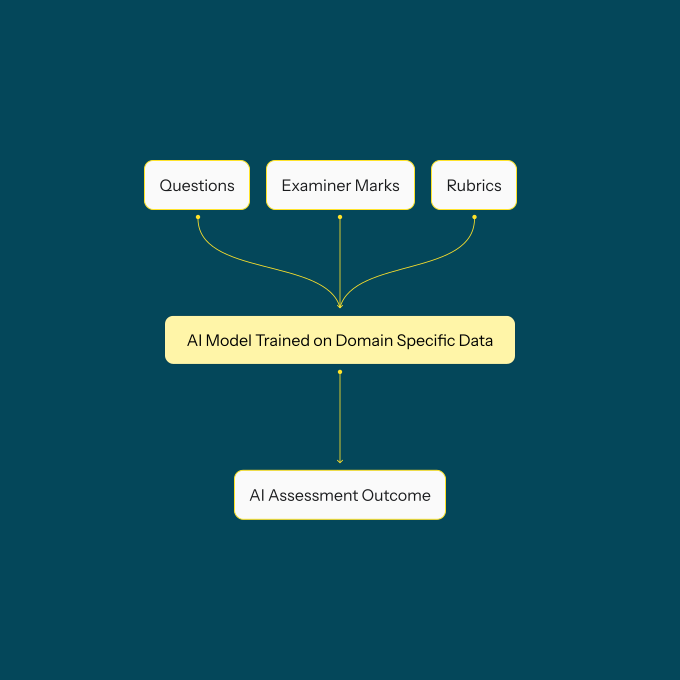
Domain-trained models evaluate multi-model responses against your specific rubrics and historical examiner judgements, not generic web data.

Regulatory compliance:
Always stay compliant with your regulators with audit trails that explain AI's recommendations, so you never have to second-guess the AI.

Performance analytics:
Gain deep visibility into individual learner and cohort performance, with distribution across every assessment cycle.

Reduction in resits & moderation:
Eliminate examiner fatigue and drift with consistent, concept-based scoring that evaluates what a student knows, not how fluently they phrase it.

LMS & E-Assessment API integration:
Connect seamlessly into your existing assessment architecture, test drivers, and workflow engines without disruption.

Centre-level performance reporting:
Access comparative analytics across test centres and cohorts to monitor quality assurance and identify systemic assessment gaps.
Why AOs choose sainaptic
Generic AI lacks domain-specificity. Sainaptic is trained directly on your questions, your mark schemes, and your senior examiners' marks. It learns your institutional logic so that every script is evaluated against your exact standard.